Tokenization in GPT ?
what is the token ?
Just like books are split into chapters and chapters into sentences, GPT splits text into tiny pieces called tokens before it can understand or generate anything.
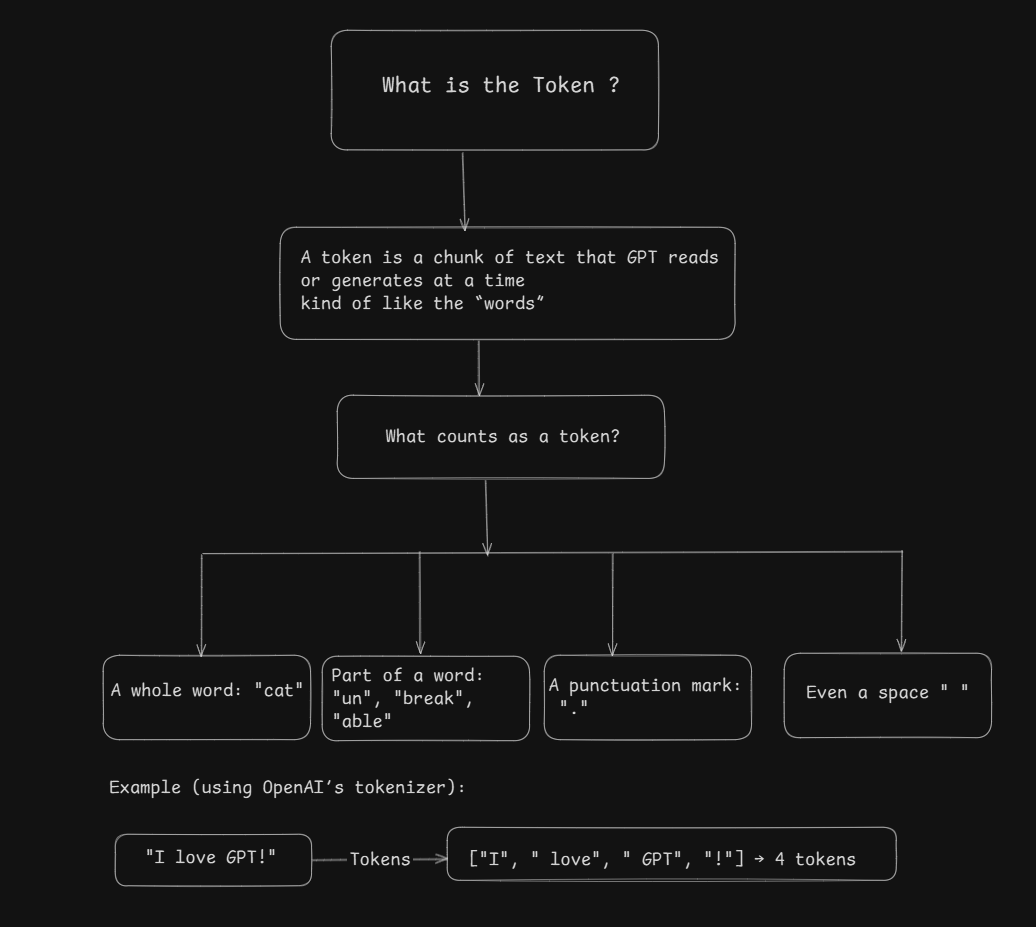
A token is a small chunk of text (could be a whole word, part of a word, punctuation, or even spaces).
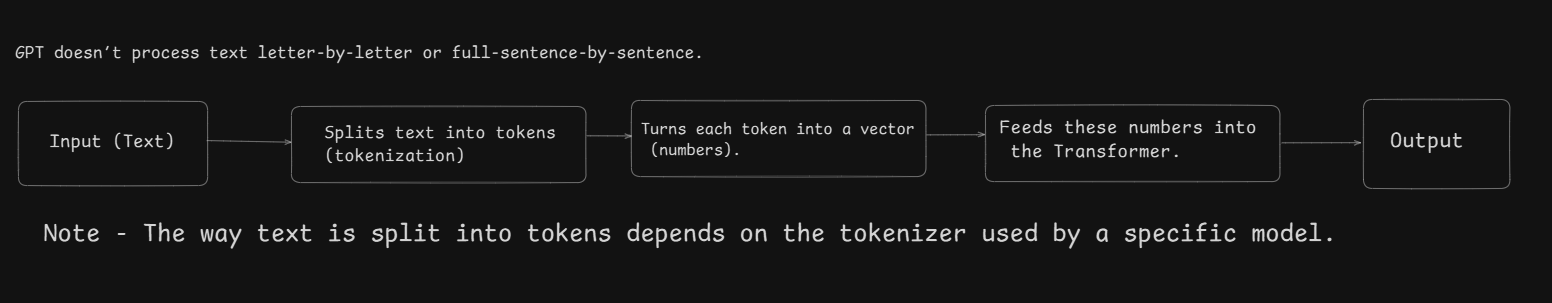
Models process tokens, not raw letters or full sentences.
Example :
| Text | Tokens | Token Count | | --- | --- | --- | | "I love AI" |
["I", " love", " AI"]| 3 | | "Tokenization" |["Token", "ization"]| 2 |
The following diagram explains tokens:
Why Tokenization Matters
How GPT understands text → converts tokens into embeddings.
Token limits → every GPT model has a max token capacity (input + output combined).
Costs & speed → more tokens = more processing time & API cost.
Conclusion :
Tokenization is the very first step in how GPT and other AI models read and process text. By breaking sentences into small chunks called tokens, the model can turn language into numbers, understand relationships between words, and generate meaningful responses.
Comments
Join the discussionNo comments yet. Be the first to comment.
